Reading the repo
How to install on macOS
bartolomeo3000/
AlphaZero-style Quoridor engine trained from zero knowledge — no human games, no heuristics. 24 h of self-play on one consumer GPU, after which it beats the previous strongest public Quoridor AI with no search at all. Play it in your browser.
PythonFlask#alphazero#board-game-ai#browser-game#deep-learning
- Difficulty
- Easy
- Time
- about 5 min
- Stars
- ★ 7
- Activity
- Updated 3 months ago
- License
- MIT
- Open issues
- 0
- Got it running
- 1 person
- Looked up
- just now
Saved setup from just now
Before you start
- Is it free?
- YesOpen source (MIT).
- Still maintained?
- Yes, activeLast change 3 months ago.
- Can I trust it?
- New, little track record7 stars, 8 months old. Look at the code and the owner before running it.
Start here
Will it work on my device?
Yes, it runs on macOS
- You'll build it yourself with Python.
4 steps on macOS
Then run bash setup.sh. It stops at the first error and is safe to run again. Servers and tests aren't started; it lists them at the end. Read it first.
Clone the repository
Needs Git: xcode-select --install
git clone https://github.com/bartolomeo3000/SigmaQuoridor.git
cd SigmaQuoridor
Install the required runtimes
Python 3.x (no version pinned)
brew install python
Install dependencies
python -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
Run it
flask run
From the README: Using the web app
bartolomeo3000.github.io/SigmaQuoridor — everything runs in your browser (ONNX Runtime Web); no data leaves your machine.
Making moves. Both move types are a plain left-click on the board:
- Move your pawn — legal destination squares are highlighted; click one. Jumps over the opponent and diagonal go-arounds are already resolved into destinations, so you just click where you want to end up.
- Place a wall — hover the groove between cells. A preview appears: orange = legal, red = illegal (overlaps, or would completely seal off a player). Orientation is inferred from which gap you're hovering, so there's no mode switch or right-click.
Controls worth knowing:
| Control | What it does |
|---|---|
| Board | 7×7 (5 walls) or 9×9 (10 walls) — 9×9 is the default and the stronger net |
| Mode | H vs AI (default), AI vs H (AI moves first), H vs H, AI vs AI |
| Agent | Per side: SigmaQuoridor (net + MCTS), MCTS (pure random rollouts), Minimax (depth 2–8) |
| Checkpoint | Per side — which exported net that side plays. In AI vs AI the two sides can pick different ones, so one checkpoint can play another |
| Simulations | Per side, 1 → 5000, default 100. This is the AI's thinking budget: 1 = raw network intuition with no search, 5000 = slow and very strong |
| Temperature | Per side, default argmax (0) — always play the most-visited move. Above 0 the side samples from its visit counts instead (visits^(1/T), same convention as mcts.py and tournament_cpp.py --temp), so repeated games diverge |
| Playback delay | Minimum time a move stays on screen while a game plays out on its own — AI vs AI, and replaying the timeline. 0 → 5 s, default 0.75 s; a search that already took longer isn't held back further. It never applies to the AI's reply to your move, which always appears as soon as the search finishes |
| ◀ ▶ / scrubber | Step one ply back or forward, or drag to any position in the game. The ← / → keys do the same |
| ▶ Play / ⏸ Pause | Start or stop auto-advance (Space). Paused at the live position, ▶ plays exactly one move; parked back in the game, ▶ replays it forward from there |
| ⇅ Flip Board | Flip orientation |
Moving from a rewound position branches the game — everything after it is discarded — so the timeline doubles as undo and redo.
- 🤖 AI vs AI — give each side its own agent, budget and checkpoint, then watch. Point the two sides at different checkpoints and you get the same head-to-head the Elo tournament runs, one game at a time at whatever speed you set. Scrub back through any game afterwards, ply by ply.
- 📊 Analysis — win-probability bars (the network's value head, plus the MCTS root value once a search finishes) and a ranked move list showing the network's prior (green) against MCTS's visit counts (red) side by side. That contrast is precisely the "search improves on intuition" step described above, made visible. You can hover a row to highlight the move, click to play it, and analyze with a different checkpoint than you're playing against.
- 🧠 NN Channels — renders all 8 input planes the network actually sees (pawns, walls, walls-in-hand, BFS distance-to-goal maps), from the side-to-move's perspective.
Try setting Simulations to 1 — that's the pure policy head, no search at all, and it still plays a respectable game.
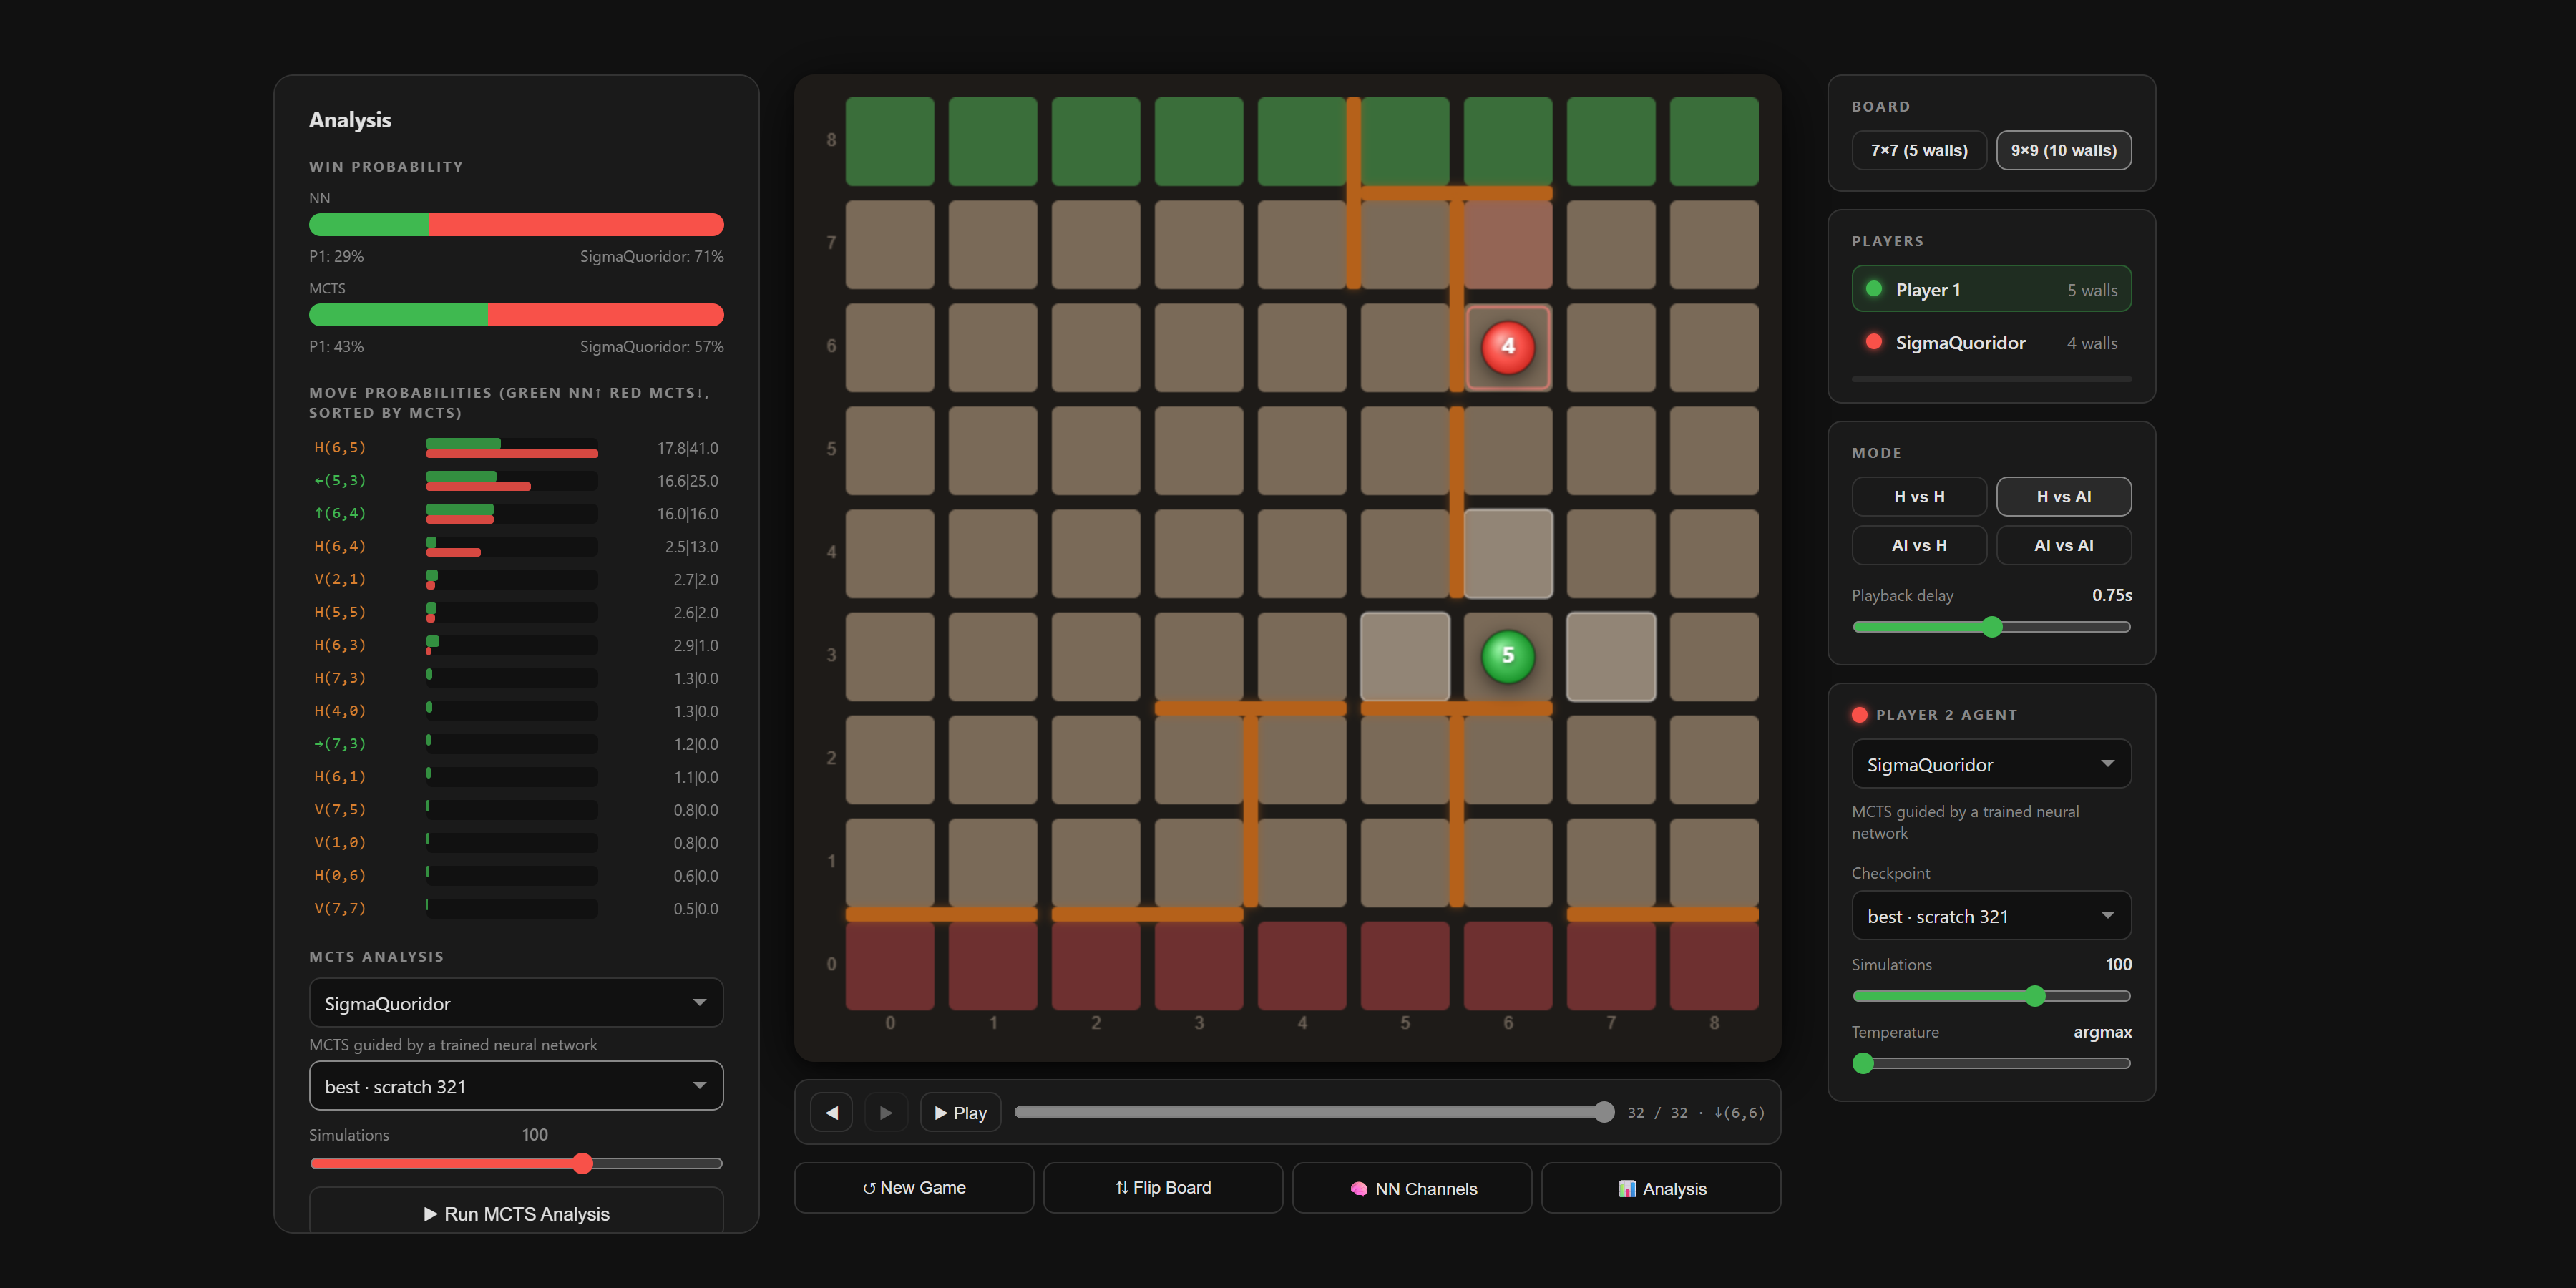
In the shot above the network can barely separate its top three — H(6,5) 17.8%, ←(5,3)
16.6%, ↑(6,4) 16.0% — and search splits them into 41.0%, 25.0% and 16.0%. It
also pulls H(6,4) up from 2.5% to 13.0%. That gap between the prior and the visit counts
is what the policy head is trained toward.
Did you get it running?
No reports for macOS yet.
Still stuck? Ask an AI
Opens a chat with this manual already filled in, for macOS. It uses your own account; gitmanual sends nothing.